What you provide: You supply raw context state (code diffs, command logs, DOM nodes, or text) alongside declared typed questions. You write zero prompt engineering instructions, few-shot formatting wrappers, or JSON schema boilerplate.
What you get back: You receive strictly typed numerical
probabilities directly in JSON: binary likelihoods (noul),
categorical probability distributions over up to 255 options
(choice), or continuous rubric evaluations
(score). The model emits zero text tokens, eliminating
parsing errors and schema hallucinations.
Operational economics & limits: Operating at sub-50 ms latency, Jev evaluates dozens of questions in a single forward pass at $0.042 per million input tokens ($42/B) with zero output token costs. Across community applications, it powers 60 FPS emulator controls and enables sub-second browser navigation. However, applying it to agent session compaction destroys prompt caches, and stripping deterministic search harnesses in games like Tetris causes instant collapse.
What is Jev? The shift from generative LLMs to typed System One judgment
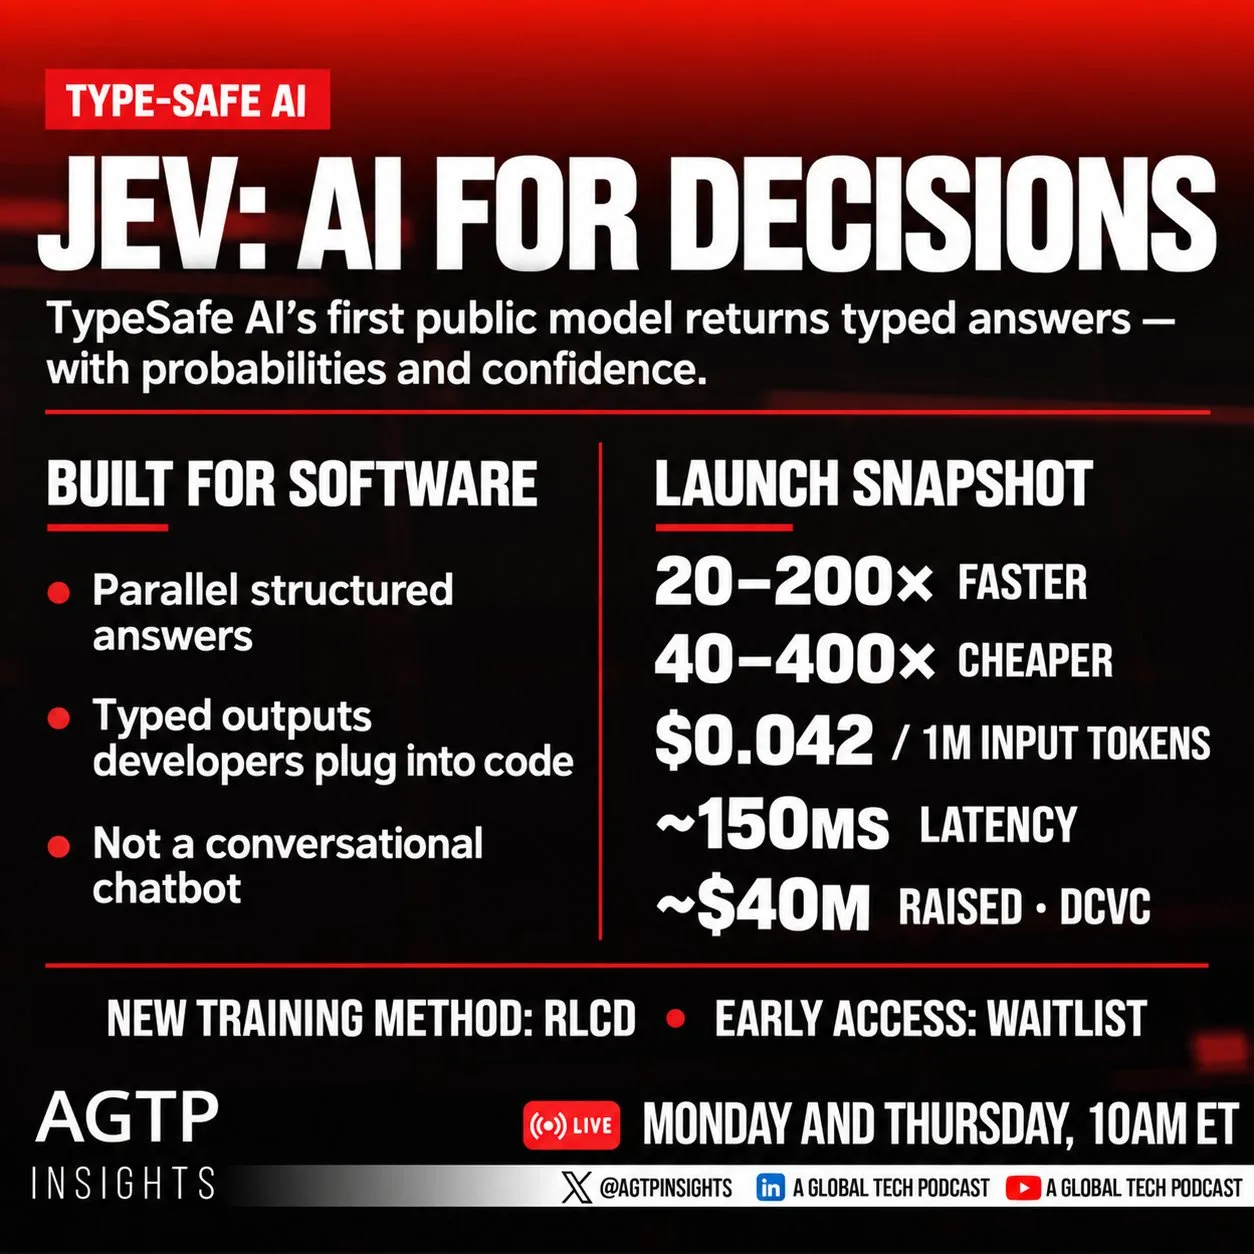
TypeSafe AI’s foundation model is named Jev. When TypeSafe AI announced the release, the first cohort of users to get access were developers who replied to the company on X explaining their specific use case. That rollout filled developer timelines with concrete examples of how people were using the model. Behind the excitement lies a consequential architectural shift in applied artificial intelligence.
To understand what Jev actually is, consider the dominant assumption of modern AI engineering: that every software task requires an autoregressive chatbot.
When engineers build automated workflows today, they typically integrate models like Claude, GPT-5, or Gemini. You supply a prompt, and the neural network predicts subsequent text token by token. For authoring prose, synthesizing documentation, or writing novel code, this autoregressiveAutoregressive GenerationThe standard LLM decoding loop where each token is predicted sequentially conditioned on all previous tokens, introducing latency and output token charges.Autoregressive Decoding → loop works well.
For production software pipelines, autoregressive decoding introduces severe friction.
The automation tax of generative models
In an automated system, most model interactions are not creative drafting tasks. Instead, they are high-frequency micro-evaluations:
- Did this shell command fail or succeed?
- Does this Git diff introduce an unhandled error path?
- Which runbook procedure matches this incident alert?
- Does this user prompt contain an adversarial prompt injection?
Routing these questions to a generative model incurs what systems engineers call an automation tax. The model takes hundreds of milliseconds to sequentially decode tokens. Next, your application must parse that unstructured text or JSON markdown block, handle trailing commas, and recover from schema hallucinations. Finally, you pay metered fees for both input tokens and generated output tokens on every single round trip.
At the opposite extreme, teams deploy regular expressions or static AST matchers. While fast and practically free, syntactic rules are fragile. They collapse when phrasing shifts, and they cannot interpret semantic context.
The System One primitive
This operational dilemma led to the creation of TypeSafe AI and its flagship System One modelSystem One ModelA non-generative neural network that performs immediate probability classification over declared schemas in a single GPU forward pass, bypassing autoregressive token-by-token generation.TypeSafe System One →, Jev.
TypeSafe AI was founded by Diogo Almeida, a co-inventor of InstructGPT at OpenAI. Having helped develop instruction tuning and RLHF alignment, Almeida recognized that modern agent pipelines misuse generative models for simple classification tasks.
The model name derives from Daniel Kahneman’s cognitive framework in Thinking, Fast and Slow:
- System Two: Slow, deliberate, sequential calculation. In AI, this corresponds to an autoregressive model generating chain-of-thought tokens or reasoning step by step.
- System One: Fast, associative, automatic recognition. In AI, this corresponds to instant probability assignment over declared options.
How Jev works: the typed wire contract
In Jev, that cognitive distinction is built into the network architecture itself:
- No text generation: Jev possesses no vocabulary generation head. It physically cannot emit text tokens, write code, or produce conversational answers.
- Single-pass parallel forward pass: It consumes the input context in a single matrix multiplication pass across its transformer weights. It computes scores across multiple parallel heads simultaneously without added token latency.
- Strict typing: Outputs are pure numerical probabilities mapped to declared schemas.
- Sub-50 ms latency and low cost: By eliminating the sequential token generation loop, inference returns in 30 to 50 ms. Pricing is fixed at $0.042 per million input tokens ($42 per billion / $42/B) with zero output token fees.
To see what this looks like in practice, consider an incident triage request. Instead of writing a prompt asking a chat model to “respond in JSON format,” an engineer posts raw logs with declared typed questions:
{
  "context": "FATAL: connection pool exhausted at db-pool-04. Retrying in 5000ms...",
  "questions": {
    "is_fatal": { "type": "noul" },
    "target_service": {
      "type": "choice",
      "options": ["cache", "database", "gateway", "auth"]
    }
  }
}
Because Jev evaluates the input directly against the schema in a single GPU pass, it returns typed probabilities with zero token hallucinations:
{
  "is_fatal": 0.98,
  "target_service": {
    "cache": 0.01,
    "database": 0.97,
    "gateway": 0.01,
    "auth": 0.01
  }
}
The model exposes three foundational primitives:
noul(Binary Probability): Evaluates a boolean proposition, returning a calibrated float from0.0to1.0.choice(Categorical Distribution): Evaluates a closed set of up to 255 discrete options, returning normalized probabilities that sum to 1.0.score(Continuous Rubric): Rates input against an ordered rubric of two to ten levels, returning an interpolated continuous score.
Because evaluations execute in parallel, asking one question or asking twenty questions over the same context costs the exact same latency.
TypeSafe AI founder Diogo Almeida introduces Jev, demonstrating why software automation requires non-generative, typed probability classifications rather than chat completions.
5-minute developer quickstart: raw API implementation
Integrating Jev requires no heavy SDKs. You can invoke the model directly via OpenRouter or TypeSafe using standard HTTP requests.
The following Python script demonstrates how to evaluate a Git diff
against parallel noul and choice questions in
a single round trip:
import os
import requests

API_KEY = os.environ.get("OPENROUTER_API_KEY")
URL = "https://openrouter.ai/api/v1/typesafe/jev"

payload = {
    "context": """
    diff --git a/pkg/auth/jwt.go b/pkg/auth/jwt.go
    --- a/pkg/auth/jwt.go
    +++ b/pkg/auth/jwt.go
    @@ -42,3 +42,4 @@ func ValidateToken(t string) (*Claims, error) {
    +    if os.Getenv("DEV_BYPASS_AUTH") == "1" { return &Claims{Role: "admin"}, nil }
    """,
    "questions": {
        "is_security_risk": {"type": "noul"},
        "severity": {
            "type": "choice",
            "options": ["none", "low", "medium", "critical"],
        },
    },
}

headers = {
    "Authorization": f"Bearer {API_KEY}",
    "Content-Type": "application/json",
}

response = requests.post(URL, json=payload, headers=headers, timeout=5)
data = response.json()

# Parse typed probabilities directly
is_risk = data["is_security_risk"] >= 0.80
severity = max(data["severity"], key=data["severity"].get)
confidence = data["severity"][severity]

print(f"Security Risk Detected: {is_risk} (Probability: {data['is_security_risk']:.2f})")
print(f"Assigned Severity: {severity} (Confidence: {confidence:.2f})")

# Deterministic branching
if is_risk and severity == "critical" and confidence >= 0.80:
    print("Action: Blocking automated PR merge. Routing to SecOps queue.")
Key implementation rules for builders
- Calibrated thresholding: Always branch on explicit
float cutoffs. In production, use
>= 0.80for automated paths and0.50to0.79for advisory alerts. - Speculative parallel fan-out: Submit all primary and secondary questions in the same payload. The GPU computes them in a single matrix multiplication pass with zero added token cost.
- No string parsing: The response keys contain raw floating-point numbers. Code branches directly without stripping markdown, extracting JSON blocks, or matching regular expressions.
The real-world exemplars: from 60 FPS emulators to sub-second browser agents
To understand why typed classification is gaining rapid adoption, look at the computational bottleneck it eliminates: autoregressive token decoding.
Frontier generative models evaluate inputs through sequential causal attention heads, generating text token by token. That creates 300 ms to 800 ms of time-to-first-token latency and unpredictable formatting overhead. When an agentic system simply needs to select an action or verify state, streaming text is an expensive anti-pattern.
Instead of generating sentences, typed evaluation processes the entire context and evaluates questions in a single parallel GPU forward pass. The open-source community quickly demonstrated how this primitive unlocks workflows that autoregressive LLMs cannot touch.
1. Sub-second browser navigation vs. vision loops
The most visible community breakthrough appears in web automation.
Frontier vision agents take multi-megabyte screenshots and query
large multimodal models, incurring 3 to 5 seconds of latency and $0.03
to $0.08 per click. The community project jev-ultrafast (browser-use/jev-ultrafast,
★4,891) inverts that architecture.
Client code extracts interactive DOM elements and accessibility trees
into a candidate action set. Jev evaluates the candidate list in a
single choice query, picking the target element in under
100 ms at $0.042 per million input tokens. Multistep form submissions
that once took 30 seconds run in under 2 seconds.
2. Real-time 60 FPS emulator and game control
To understand why typed classification is gaining rapid adoption, examine gaming emulation. In real-time gaming, autoregressive token decoding is a non-starter.
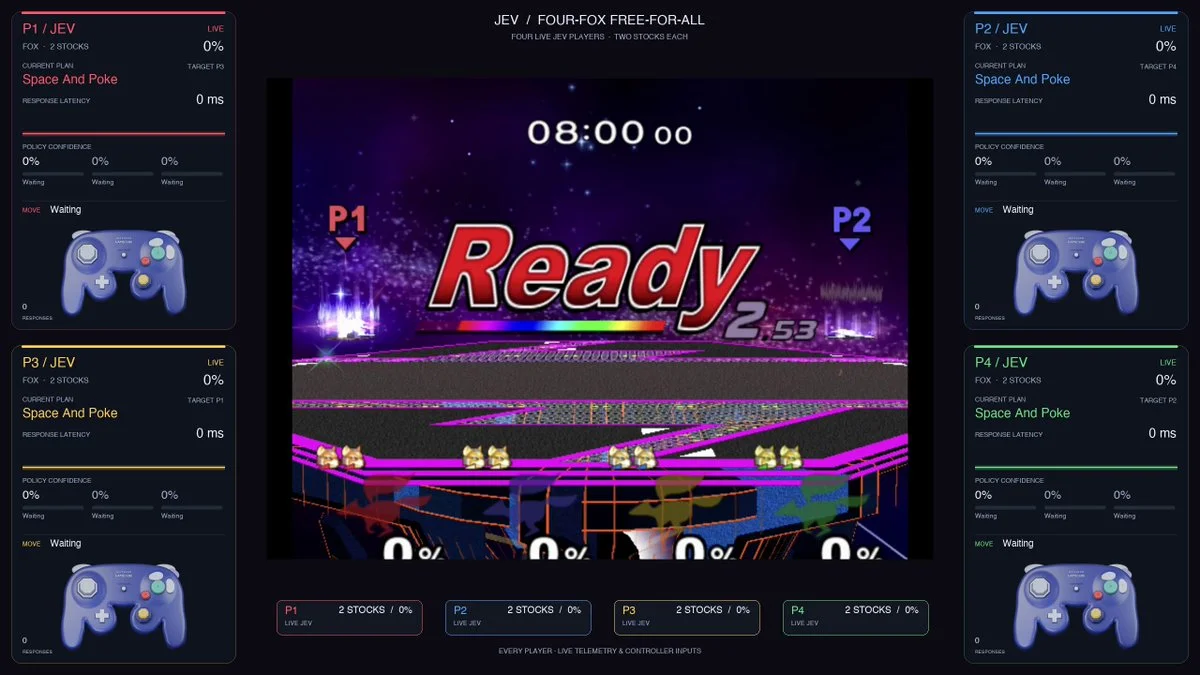
When developer Mau Baron (@maubaron) launched his viral Super Smash Bros. Melee experiment (watch on X), he demonstrated an autonomous system where Jev controlled all four characters simultaneously in a live free-for-all match. Rather than playing against scripted bots, the model played entirely against itself, deciding the optimal counter-move for every character within fractions of a second.
In discussions detailing the implementation, Baron and other emulator developers outlined key architectural decisions:
- Bypassing computer vision for raw RAM parsing: Traditional gaming agents feed video frames to heavy vision language models (VLMs), incurring 500 ms to 1,500 ms of latency and burning multimodal tokens. Instead, the setup reads Dolphin emulator RAM directly into a structured text state: exact character coordinates, velocities, percentage damage, animation frames, and projectile hitboxes. This gives the model deterministic, auditable observations without pixel noise or OCR hallucinations.
- Translating probabilities into controller macros:
Jev evaluates candidate moves using typed
choicequestions over action schemas. In his implementation notes, Baron highlighted tactical filtering: the model evaluates candidate actions to actively filter out predicted self-destruct trajectories and fatal off-stage positions before dispatching controller inputs. - Unlocking 60 FPS reaction loops: GameCube emulation runs at 60 frames per second (16.6 ms per frame). Because Jev bypasses token generation, evaluation latency drops to single-digit or low double-digit milliseconds, allowing instant defensive counters and attacks.
- Microeconomics at scale: The four-player match consumed over 22 million input tokens across continuous high-frequency evaluations. Yet the entire run cost only a couple of cents (approximately $0.92 at $0.042 per million input tokens, with zero output token fees). Routing 22 million tokens through frontier generative LLMs would cost over $55 and stall execution.
- System One reflex layer: Baron noted that Jev does not replace frontier reasoning models like GPT-6 Astra, but acts as a tactical reflex layer. While the memory adapter is game-specific, the reflex pattern ports directly to robotics and high-frequency automation.
An identical pattern powers typesafe-mario (fhshaik/typesafe-mario,
★260). The autonomous agent feeds live NES memory snapshots into a
choice primitive across controller inputs
[A, B, LEFT, RIGHT, UP, DOWN, NONE]. Inference resolves in
under 16 ms on GPU, keeping Mario aligned with native 60 FPS cycles.
TypeSafe AI founder Diogo Almeida demonstrated the same architecture
with an interactive Doom agent navigating 3D combat encounters without
token generation lag.
Architectural cautionary tales: where newly popular techniques fail
As fast classification primitives surged in popularity, developers rushed to deploy them across every domain that felt too slow or expensive for frontier generative LLMs. Two viral experiments–one in agent context compaction, and one in real-time game control–revealed stark empirical boundaries. Examining why both attempts failed provides a masterclass in how to apply these newly popular techniques with proper investigation and caution.
1. The session compaction anti-pattern and cache destruction
In developer tooling, multiple projects attempted to apply Jev to
agent context management. The most prominent example is
fast-jev-compaction (tamaratran/fast-jev-compaction,
★2,790).
The tool attempts to solve context window exhaustion in long-running
Claude Code and Codex sessions. Instead of summarizing entire histories
with a heavy generative model, it scores conversation chunks with
parallel noul questions to discard compiler noise, terminal
output, and tool return data.
Although promotional claims promise dramatic token savings, this technique introduces an attractive nuisance and a serious engineering anti-pattern. Understanding why reveals fundamental truths about how autonomous coding agents function.
Teknium’s empirical compaction evaluation
The most definitive empirical assessment came from Teknium, co-founder of Nous Research (creators of the Hermes model family).
Teknium benchmarked Jev compaction against Hermes Agent’s production compaction harness in an open, reproducible evaluation (Hermes Agent PR #116246).
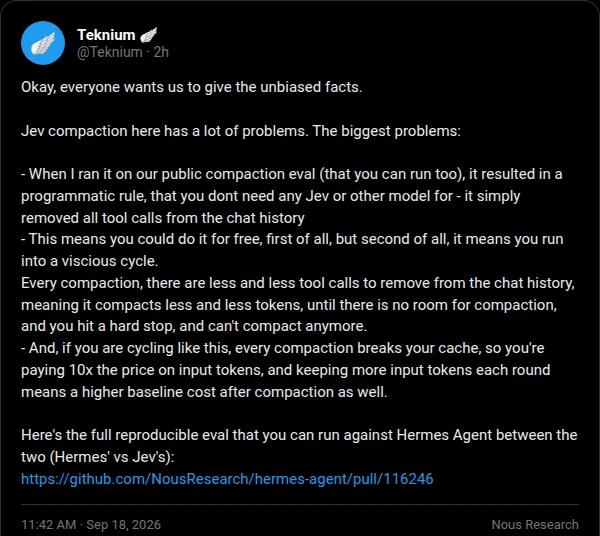
Teknium posted the core critique of Jev context compaction:
- When I ran it on our public compaction eval (that you can run too), it resulted in a programmatic rule, that you dont need any Jev or other model for. It simply removed all tool calls from the chat history.
- This means you could do it for free, first of all, but second of all, it means you run into a viscious cycle. Every compaction, there are less and less tool calls to remove from the chat history. That means it compacts less and less tokens, until there is no room for compaction, and you hit a hard stop, and can’t compact anymore.
- And, if you are cycling like this, every compaction breaks your cache. So you are paying 10x the price on input tokens, and keeping more input tokens each round means a higher baseline cost after compaction as well.
Here’s the full reproducible eval that you can run against Hermes Agent between the two (Hermes’ vs Jev’s): Hermes Agent PR #116246.
These three empirical points dismantle the premise of neural context compaction:
- Trivial heuristic collapse: If an ML model converges to stripping all tool calls, paying API fees to run inference is wasteful. A single line of deterministic code performs that operation instantly at zero cost.
- The diminishing returns wall: Pruning tool calls only works while uncompacted tool calls exist. As the session progresses, the token yield shrinks to zero, leaving the agent stranded when context fills.
- The severe cache invalidation penalty: Modern frontier LLM providers (Anthropic, OpenAI, DeepSeek) offer massive discounts for prompt prefix caching. Neural compaction mutates past context non-deterministically, destroying the prompt cache on every round trip. As benchmarked in Hermes Agent PR #116246, callers lose prefix cache discounts and pay full un-cached rates while carrying an inflated baseline token count.
The causal ledger and subtle diagnostic loss
Beyond token economics, session compaction damages agent reasoning:
- Context amnesia and broken causal chains: In an agentic coding loop, tool calls and execution logs represent an empirical causal ledger. When an agent runs a compiler, reads a panic trace, and modifies code, that failure output is the causal justification for the change. If a classifier prunes the failure because it looks repetitive, the agent suffers causal amnesia, frequently reverting valid edits or thrashing in retry loops.
- The subtle diagnostic trap: The most critical bugs in software development are signaled by subtle, low-salience warnings (deprecation notices, lockfile version drifts, memory alignment hints). To a semantic classifier, a single warning line in a 400-line test log looks like boilerplate noise. Once purged, that diagnostic signal is permanently lost.
- Non-deterministic working memory: Delegating memory eviction to a neural model makes the agent’s working memory substrate non-deterministic. A session might succeed or fail depending on whether a probability score fluctuated between 0.79 and 0.81.
Deterministic compaction is strictly superior
Context compaction is a real problem, but it is already solved cleanly by deterministic code:
- Head and tail line caps: Preserving the first 20 lines (the command invocation) and the last 50 lines (the panic or assertion trace) captures actionable failures without transmitting thousands of passing tests.
- ANSI stripping and whitespace deduplication: Removing escape sequences and redundant blank lines substantially shrinks log token volume without losing diagnostic characters.
- Disk offloading with immutable URI pointers:
Writing verbose test logs to disk and leaving a file pointer in context
(
log: /scratch/test-run-42.log) keeps context clean while allowing the agent to view exact line slices on demand.
Deterministic compaction costs $0, executes in under 1 ms, exhibits zero variance, and never deletes the stack frame you need.
2. The Tetris harness illusion and action-space collapse
The second critical cautionary tale emerged from real-time gaming benchmarks.
Software entrepreneur Tony Dinh (@tdinh_me, creator of TypingMind) published a viral real-time benchmark: a head-to-head Tetris battle pitting TypeSafe Jev against Claude Haiku 4.5 (initial demonstration on X). Because both models competed simultaneously in real time, the benchmark promised to measure both raw inference speed and game intelligence.
Initial results looked extraordinary: Jev responded in ~200 ms, keeping pace with live piece drops and placing tetrominos cleanly.
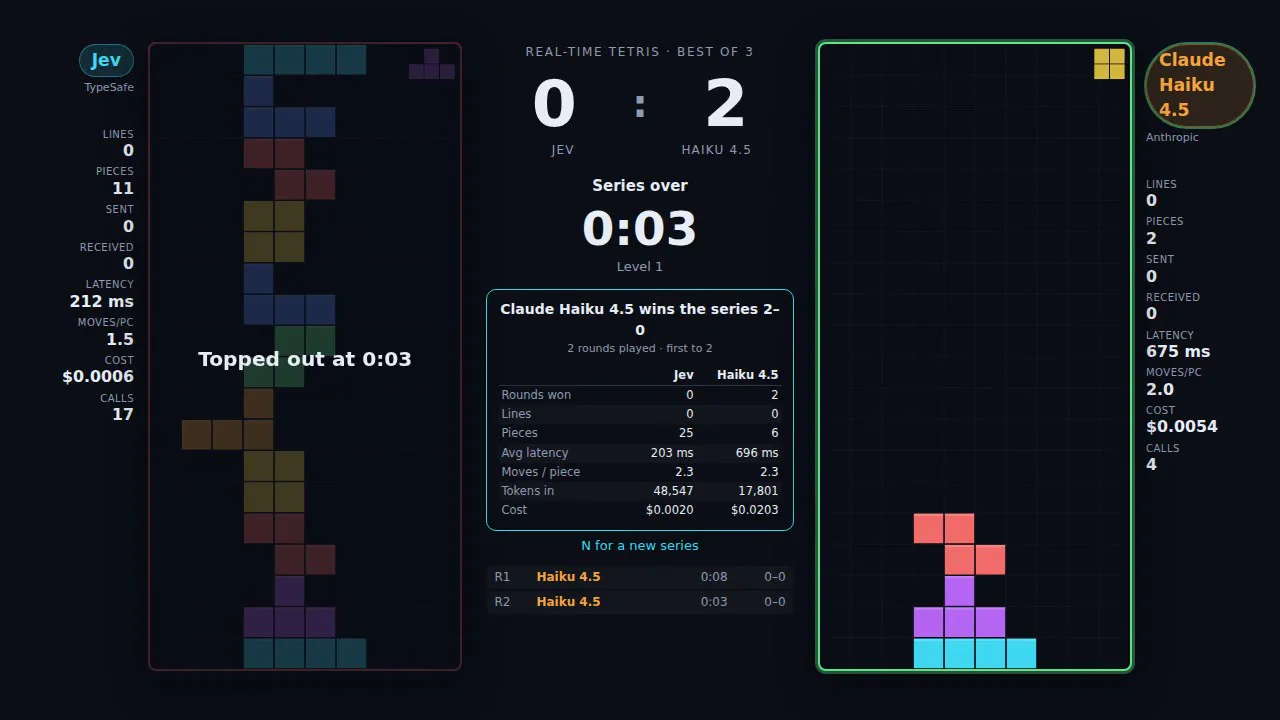
Tony Dinh’s empirical reality check
When Dinh investigated his own test harness, he uncovered an essential architectural illusion. He published an honest, rigorous post-mortem (read on X):
“Ok I made a mistake,” Dinh acknowledged.
“The game harness was doing a lot of heavy lifting for both models by preparing optimal options for Jev/Haiku to pick from, given a game state.
If I change the harness to provide only game rules and game state, and only allow Jev to decide the control buttons (left/right/rotate/drop), it pretty much becomes useless.”
When Dinh removed the algorithmic pre-filtering and gave Jev direct controller access, the model suffered total collapse:
- Immediate game over: Jev lost the series 0-2, topping out in exactly 3 seconds (Round 2 lasted 0:03).
- Zero spatial navigation: Instead of rotating and maneuvering shapes into open valleys, Jev repeatedly triggered the default drop in column 5, erecting a single vertical tower until the board overflowed.
- The illusion of intelligence: The original “intelligent play” was not coming from Jev’s internal reasoning. It was coming from the deterministic TypeScript harness that calculated valid placements, pruned illegal moves, and served a curated multiple-choice menu.
Why fast reflex classifiers cannot plan
Dinh’s finding exposes a foundational boundary of System One foundation models:
- System One is a pattern switchboard, not a search tree: Fast classifiers evaluate prompt states against candidate options in single forward passes. They compute instant heuristic likelihoods, but they do not maintain internal state trees, backtrack across alternative futures, or simulate spatial physics.
- The action-space explosion trap: When an action
space is discrete, bounded, and semantically distinct
(
cancellation,refund,technical_support), typed classifiers excel. But when an agent must execute long chains of unconstrained atomic controls ([LEFT, LEFT, ROTATE, ROTATE, DROP]) where each move alters future geometry, the action space explodes combinatorially. A reflex classifier lacking lookahead degenerates into random thrashing. - The harness attribution error: In AI development, engineers frequently credit the model for victories achieved by the scaffolding. If code generates candidate placements, validates geometry, and filters out blunders, the deterministic harness performs virtually the entire task. Mistaking candidate ranking for spatial intelligence leads teams to deploy reflex models into open-ended planning tasks where they fail instantly.
3. Architectural discipline: how to apply newly popular techniques safely
Synthesizing the lessons from Teknium’s compaction benchmarks and Tony Dinh’s Tetris post-mortem establishes four non-negotiable rules for engineering teams:
- Never delegate deterministic tasks to neural classifiers: If an operation can be solved with string slicing, regular expressions, AST parsers, or line caps, write the code. Paying an AI API to strip tool calls or parse JSON is an architectural flaw that adds latency, cost, and non-deterministic failure modes.
- Keep spatial simulation and search in deterministic code: If your problem involves geometry, multi-step game physics, route planning, or chess trees, use algorithmic search (A*, Minimax, BFS, or spatial collision physics). Use the fast classifier solely to evaluate heuristic tie-breakers across the top candidates produced by the algorithm.
- Protect prefix prompt caching at all costs: Any pipeline that repeatedly mutates past conversation context or rewires prompt prefixes throws away 80% to 90% caching discounts (see Anthropic prompt caching documentation). Working memory should append immutably; verbose logs belong on disk behind URI pointers.
- Audit what the harness does before claiming model capability: Always test your system with the scaffolding removed or randomized. If degrading candidate pre-filtering causes your model to collapse, you have built a deterministic algorithm with an expensive neural rubber stamp, not an autonomous agent.
Production decision rules: asymmetric routing and ambiguity gating
Where typed models excel is high-throughput classification over extracted, bounded decision spaces. Two operational patterns demonstrate how to deploy them safely.
1. The asymmetric error principle in task routing
A common requirement in agent workflows is routing an operational task description to the specific runbook, governance procedure, or skill designed to handle it.
Keyword search over documentation catalogs frequently breaks down when engineers use natural language rather than exact identifiers. A typed model evaluates natural language descriptions against catalog schemas cleanly.
However, the cost of classification errors in automation is sharply asymmetric:
- False positive routing: If the model routes to procedure A instead of procedure B, an engineer spots the mismatch during execution. The cost is minor redirected search friction.
- False negative abstention: If the model returns “no procedure applies” when a mandatory governance procedure actually exists, the agent assumes the workspace is unregulated and executes an unreviewed, ad-hoc change.
Because an improper abstention can bypass safety controls, the threshold for returning “none” cannot be a simple majority probability. In production routers, a confident “none” (confidence ≥ 0.85) is accepted; an uncertain “none” automatically falls back to returning the top candidate procedures for human confirmation.
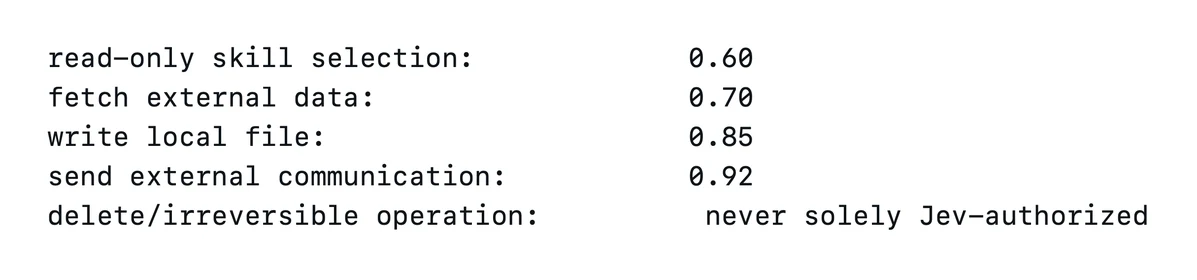
2. Ambiguity gating in interactive user loops
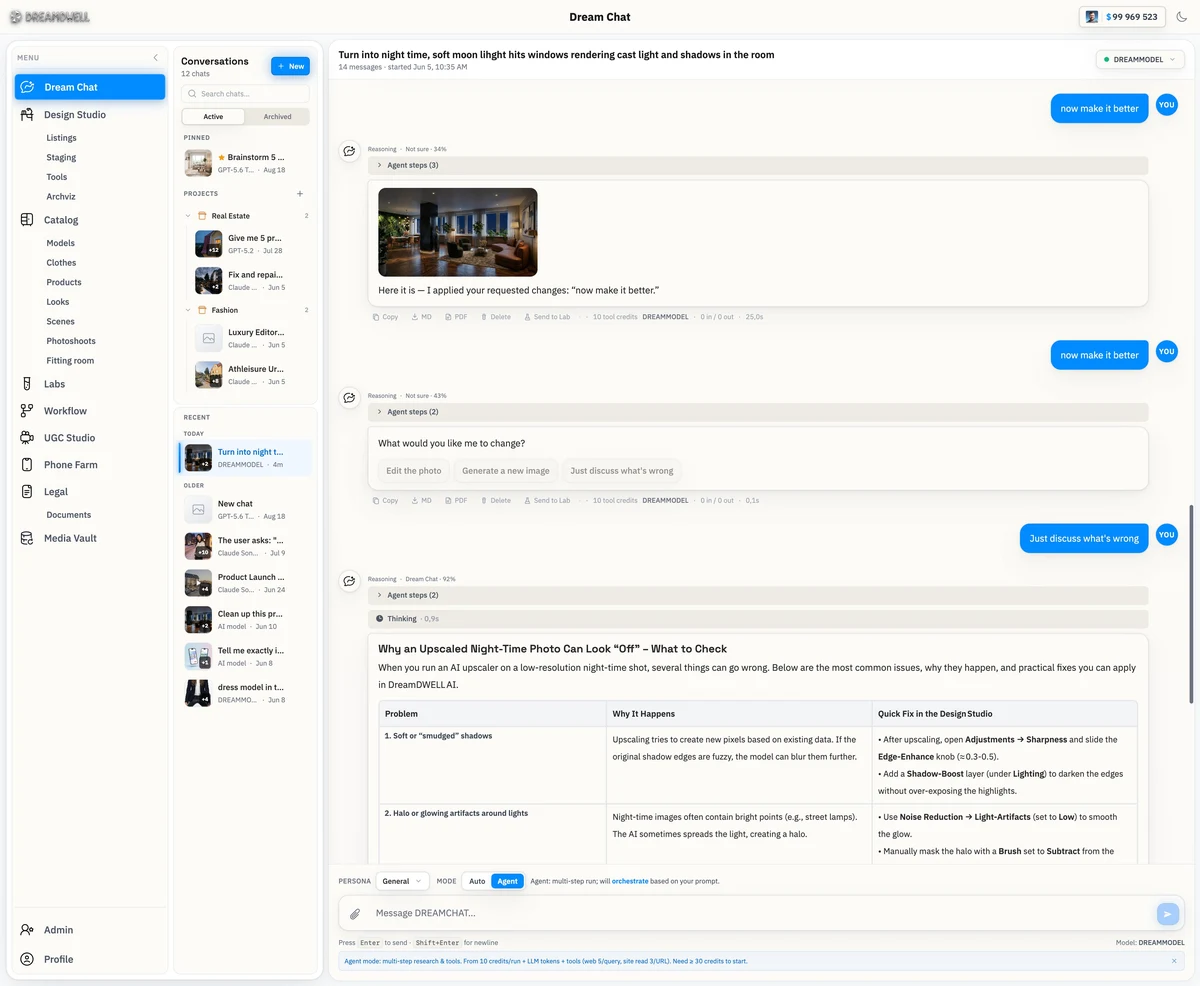
In creative or conversational applications, users frequently provide vague instructions such as “now make it better.” Passing ambiguous prompts directly to expensive generative models burns API credits on low-quality guesses.
Practitioner Pavel Sich implemented Jev as an ambiguity gate in DreamChat. When user prompt clarity yields low confidence (e.g., 34%), the system intercepts the request and presents a structured disambiguation menu.
Empirical benchmark: adversarial invoice sorting and the “certain, and wrong” trap
One developer’s list of projects built on Jev grew from 46 to 160 in three days. I wanted a measurement to go with the excitement.
Jev takes text, a question, and a list of possible answers. It picks one and reports its confidence.
I tested the vendor’s showcase task: sorting invoices. My first dataset was too easy - all six models scored 100%. I rebuilt it.
Fifty documents across six types. In 32, the obvious clue is a lie.
A “PROFORMA INVOICE” billing for goods already shipped. A purchase order with prices that make it look like a quote. An “INVOICE SUMMARY” explicitly saying it isn’t a request for payment.
Ten languages. OCR errors. An amount written out in words. Three documents without obvious keywords, including a freelancer’s invoice written as an email.
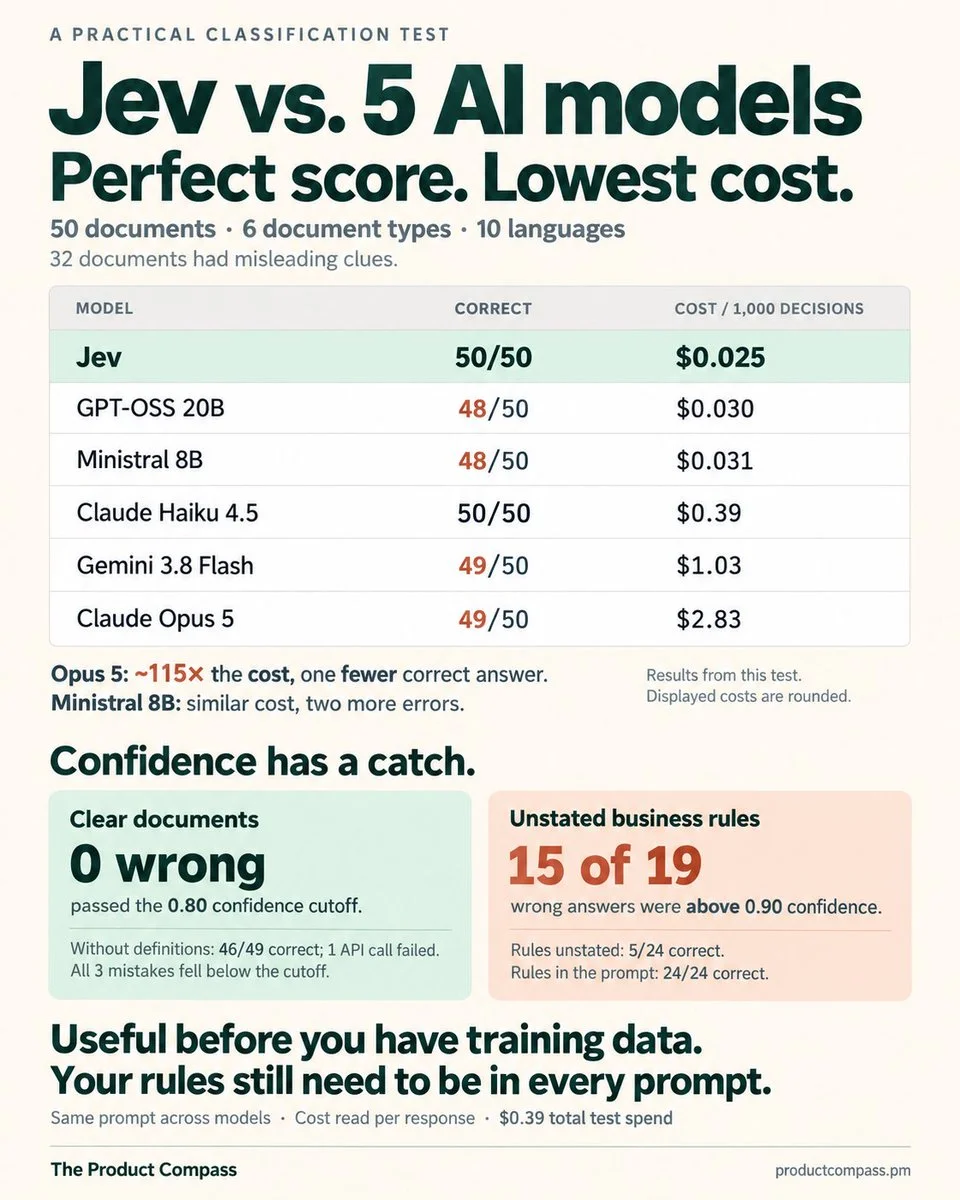
Correct answers, followed by cost per 1,000 decisions:
- Jev: 50/50, $0.025
- GPT-OSS 20B: 48/50, $0.030
- Ministral 8B: 48/50, $0.031
- Claude Haiku 4.5: 50/50, $0.39
- Gemini 3.8 Flash: 49/50, $1.03
- Claude Opus 5: 49/50, $2.83
The “444x cheaper” claim compares Jev with Fable 5.1 and GPT-6 Astra. My Opus comparison also produced a huge multiple, but Opus isn’t the most useful baseline here.
Against Ministral 8B, which you can run locally, Jev cost about 20% less and took about 90 ms longer per decision, sending one question at a time. Batched, Jev answered 32 questions in roughly the time it answered one.
Then I removed the definitions and gave Jev only the six category names.
It got 46/49 completed requests right; one API call failed. Every mistake fell below 0.80 confidence. Correct answers averaged 0.97.
A 0.80 cutoff would have flagged all three mistakes. Nothing wrong got past the line in this run. The failed call needed separate handling.
Then I tested 24 support messages with house rules that contradicted the obvious answer - duplicate charges going to support instead of billing, for example.
- Rules in the prompt: 24/24 correct.
- Rules left unstated: 5/24.
Of the 19 wrong answers, 15 came back above 0.90 confidence.
Certain, and wrong.
Confidence caught every invoice error here. It did not reliably flag errors caused by missing business rules.
Those rules must be supplied with each request. Corrections don’t carry over between calls on their own.
I also tried labeled examples instead of rules: Jev scored 13/24; Ministral 8B scored 18/24.
For real invoice sorting, you want three things:
- A record of each input, decision, and confidence score.
- A threshold for sending uncertain decisions to a person.
- A system that improves as humans correct it.
Jev offers a starting point for the first two. The third needs a feedback loop: collect corrections, update the system, and test the changes. A dedicated classifier with a retraining pipeline is one established option.
Before you have training data, when your rules are in plain English and you need something running this afternoon, Jev looks useful.
In my invoice test, it matched the best accuracy at the lowest cost.
You still have to write down your rules. High confidence won’t tell you which ones you forgot.
Alternatives, competition, and fine-tuning: when to graduate from Jev
Production classification requires three structural capabilities:
- A persistent decision ledger: Logging raw inputs, category choices, latency, and confidence distributions.
- Calibrated threshold gating: Routing low-confidence outputs (< 0.80) or sensitive edge cases to human specialists.
- A feedback retraining loop: Collecting human corrections, updating system intelligence, and testing regressions against historical gold sets.
Jev provides a fast starting point for the first two capabilities, but it provides no native mechanism for the third.
Updating Jev requires adding more sentences to the prompt. Over time, prompt bloat increases input token fees and introduces unpredictable rule interactions.
When systems scale beyond day-one prototypes, several established alternatives provide superior long-term economics and deterministic governance.
In empirical evaluations, the open-weights ecosystem actively
measures these boundaries. In the multi-candidate S1Bench benchmark (@ItsCuthulhu), Jake
Cuth measured 24 open-weight decision models against TypeSafe Jev on
dedicated NVIDIA DGX Spark infrastructure across 1,999 decisions. The
results illustrate a sharp Pareto frontier: TypeSafe Jev anchored
accuracy at 77.5% at 2.4 decisions/s (0.42 s per item, ECE 0.076). While
bi-directional encoders like open-jev-deberta achieved 37
decisions/s (0.03 s per item), accuracy collapsed to 52.4%. Conversely,
large adaptations like simplejev-qwen38-27b reached 75.8%
accuracy at 1.6 decisions/s, but demanded a 27 B parameter memory
footprint on dedicated GPU clusters.
Building on this scale, Archer Hume and Doccy healthcare demonstrated Solomon 27b, an open-weight alternative adapted from Qwen3.8 27b. Solomon 27b brings native multimodal evaluation, a 265k context window, multi-choice tagging, and evidence pointer spans to clinical and document classification without autoregressive decoding latency.
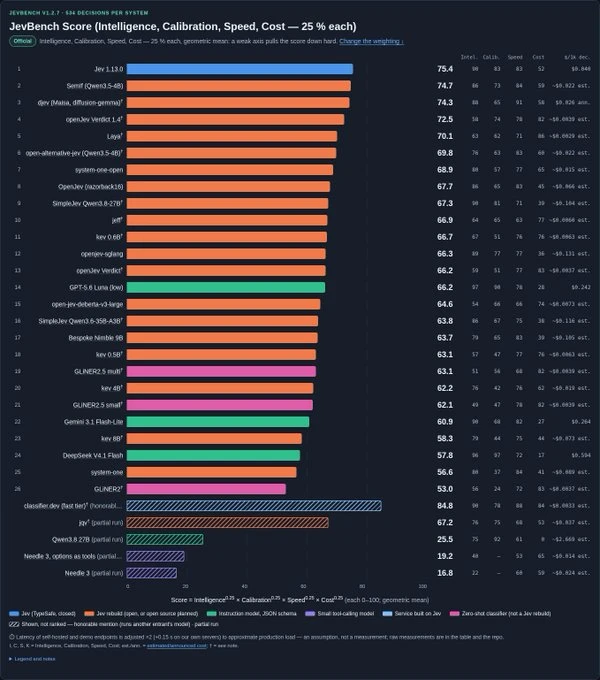
In independent multi-dimensional testing, Benchmark Heaven published JevBench v1.2 (results JSON), evaluating 42 decision models across 534 tasks (including 220 hard decisions). Rather than ranking solely on raw accuracy, the benchmark computes a geometric mean across four balanced axes: Intelligence, Calibration, Speed, and Cost (25% each, see JevBench scoring harness).
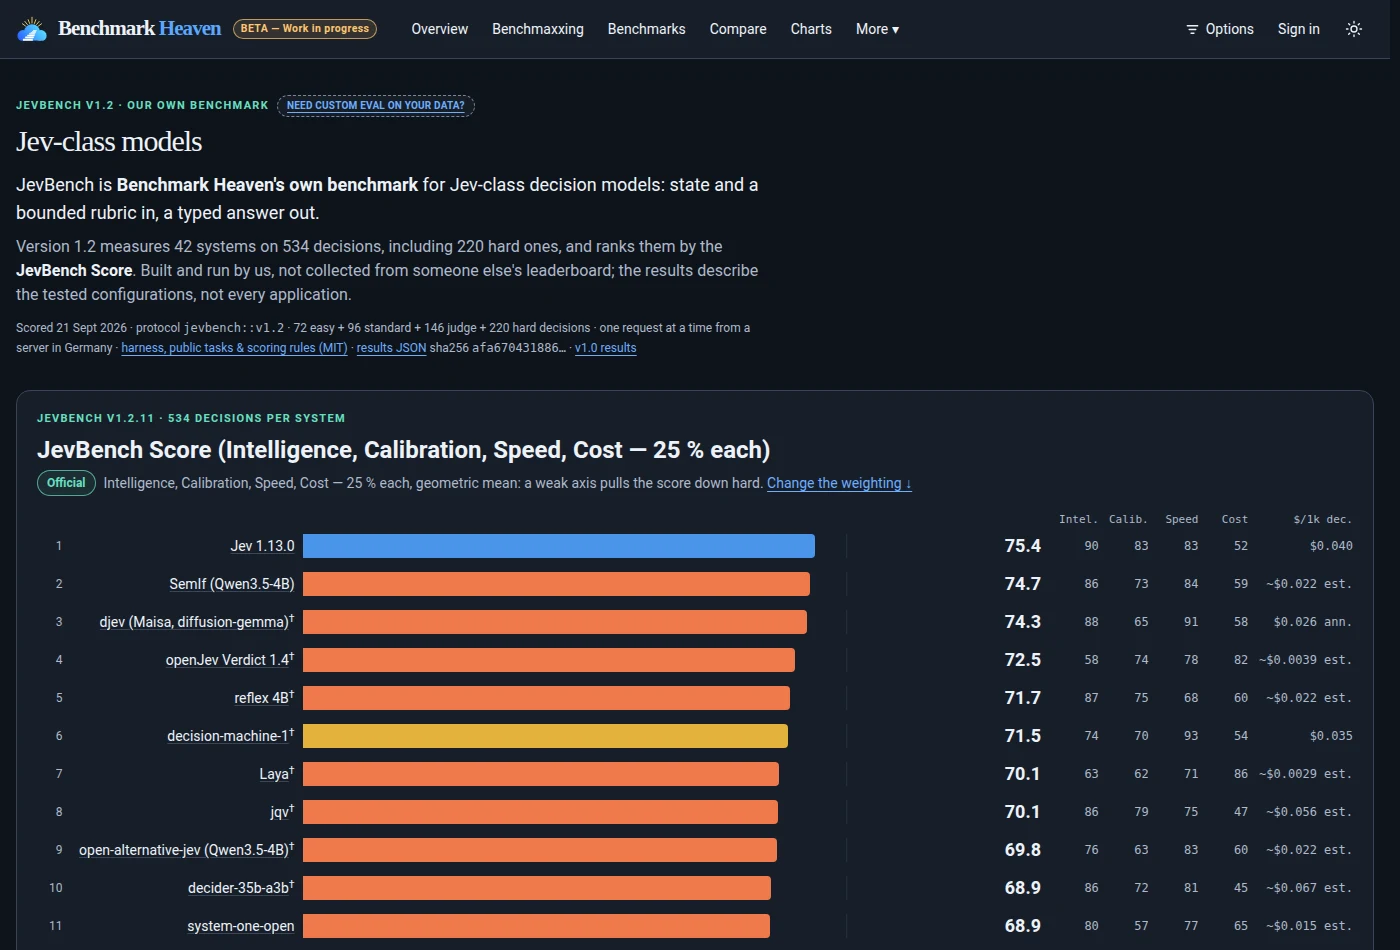
The JevBench v1.2 leaderboard illuminates key production trade-offs across open rebuilds and hosted endpoints:
- Jev 1.13.0 retains the top composite score (75.4): TypeSafe’s hosted engine leads overall intelligence (90.4) and calibration (82.7), but ranks lower on cost (52.0 at $0.040 per 1,000 decisions as measured by Benchmark Heaven).
- SemIf (Qwen3.5-4B) captures rank 2 (74.7): Theodore Lee’s open-source rebuild reaches 85.9 intelligence and 83.7 speed, cutting costs to ~$0.022 per 1,000 decisions on DeepInfra endpoints.
- djev (Maisa) secures rank 3 (74.3): Built on diffusion-gemma weights, djev posted the highest raw speed score (91.4) among frontier alternatives at an announced $0.026 per 1,000 decisions (djev documentation).
- Extreme cost efficiency in encoder rebuilds: OpenJev Verdict 1.4 (RLCD ModernBERT-151 M) achieves rank 4 with an 82.4 cost score (~$0.0039 per 1,000 decisions), while Laya (ModernBERT-large) costs ~$0.0029 (Hugging Face models).
1. Fine-tuned encoder architectures (ModernBERT, DeBERTa-v3)
For high-volume production routing, dedicated bi-directional encoders represent the industry gold standard (ModernBERT on Hugging Face):
- Inference speed: ModernBERT and DeBERTa-v3 process classification decisions in sub-5 ms on commodity CPU or low-power GPU instances.
- Zero marginal cost: Self-hosted encoders incur zero per-token API charges, reducing operational costs to fixed compute.
- Data privacy and residency: Financial records, invoices, and customer communications remain entirely within your secure VPC without external network transmission.
- True active learning: When human reviewers correct misclassifications, those pairs feed directly into automated LoRA or head retraining pipelines. The model bakes company exceptions permanently into its weights.
2. Few-shot contrastive classifiers (SetFit)
When you possess only a handful of examples per category, SetFit (Sentence Transformer Fine-Tuning) offers an efficient middle ground (SetFit Documentation):
- Sample efficiency: SetFit achieves high classification accuracy with as few as 8 to 16 labeled examples per class.
- Prompt-free operation: Business rules are encoded into vector space mappings rather than lengthy prose prompts.
- Lightweight deployment: Inference runs locally in Python with minimal memory overhead, eliminating third-party API dependencies.
3. Local SLMs with constrained logit decoding
Small generative models running locally via vLLM, SGLang, or Outlines offer flexible reasoning with strict output contracts (Outlines Structured Generation):
- Constrained logit masks: Software forces the model to select exclusively from valid schema choices in a single token step.
- Superior few-shot induction: Models like Ministral 8B and Qwen 2.5 7B induce patterns from labeled examples more effectively than pure probability classifiers.
- Hybrid extraction: An SLM can classify an invoice and extract invoice numbers, tax amounts, and vendor names in the same forward pass.
Architectural lifecycle: selecting the right tool
Choose your classification strategy based on development phase and operational volume:
- Day 1 (Prototyping and Cold Start): When you have zero labeled training data, rules written in plain English, and need a working service today, Jev is compelling. It matches frontier accuracy at $0.025 per 1,000 decisions with calibrated confidence gating.
- Day 30 (Emerging Volume and Edge Cases): As human reviewers log hundreds of domain-specific exceptions, prompt text becomes difficult to maintain. Deploy SetFit or few-shot Ministral 8B to capture nuances from real examples.
- Day 90+ (Scale and Strict Governance): When processing millions of documents under SOC2, HIPAA, or strict latency requirements, deploy dedicated ModernBERT or fine-tuned DeBERTa-v3 models inside your private infrastructure.
The honest counterweight: where deterministic code wins
Every tool has an operational boundary. In production systems architecture, every candidate model integration must pass the deletion test: would deleting the model leave the requested outcome unmet or unproven?
If native deterministic code can achieve the outcome reliably, using a neural model is an architectural flaw.
1. Mutation testing destroys model opinions
Where a deterministic oracle exists, using a machine learning model is an anti-pattern. Consider test suite evaluation: you could ask a model to “judge whether this test suite is rigorous.” But that judgment is merely an unverified opinion.
In contrast, mutation testingMutation
TestingAn empirical verification
technique where automated tools inject deliberate syntactical faults
into source code to verify whether existing tests actively fail and
catch the
defect.Mutation
Testing → tools (such as cargo-mutants or
stryker) systematically insert syntactical faults into the
codebase and execute the test suite. If a mutant survives, the test
suite demonstrably failed to catch broken code.
That is an empirical mathematical proof, not a probability. A model has no place in the mutation loop.
2. Sequential ordering and execution traces
A critical failure mode of typed classification models is reasoning over temporal sequence order.
When evaluating system execution logs, models can identify individual
matching tokens (such as detecting error or
changed=0). However, when a specification requires
verifying that Phase A completed before Phase B began, models frequently
fail. Sequence tracking belongs in deterministic log parsers and state
machine validators.
3. What stays in code
Deterministic algorithms belong in native code:
- Set reconciliation: Determining diffs between deployed resources and Git state belongs in hash comparisons and set theory.
- Arithmetic & thresholds: Comparing latency
percentiles, error budgets, or billing totals belongs in standard
relational operators (
>,<). - Graph traversal: Dependency ordering and topological sorting in build systems belong in Kahn’s algorithm, not in a neural network.
- Lexicon lookups: Verifying exact identifiers, environment variables, or schema fields belongs in map lookups.
Replacing any of these with a model introduces latency, variance, and cost with zero engineering benefit.
4. Correcting the limits: what 255 actually bounds
Launch-week commentary frequently claimed Jev caps requests at “255 questions per API call,” misinterpreting the vendor announcement.
That figure was real, but it described candidate choices rather than question count.
The vendor
launch post specifies that 255 caps candidate options within
a single choice question. You cannot submit a
question with 300 enumerated categories.
Valyu’s practitioner guide documents no ceiling on question count; the binding constraint is a token budget:
- 64,000 total tokens covering the input state and all submitted questions combined.
- 32,000 tokens for the state plus the single longest question.
Practitioner video teardowns and live demos from X
Beyond static commentary, practitioners published video teardowns, benchmark sessions, and integration walkthroughs demonstrating how System One models behave under real workloads:
Official launch walkthrough showing how Jev evaluates game state trees at 60 FPS without autoregressive token generation latency.
Controls four characters simultaneously in real-time, playing against itself directly from Dolphin RAM. Evaluates candidate moves at 60 FPS across 22 million tokens for under a dollar.
Critical hands-on teardown exploring whether fast classification solves real engineering problems or merely shifts prompt engineering to network coordination.
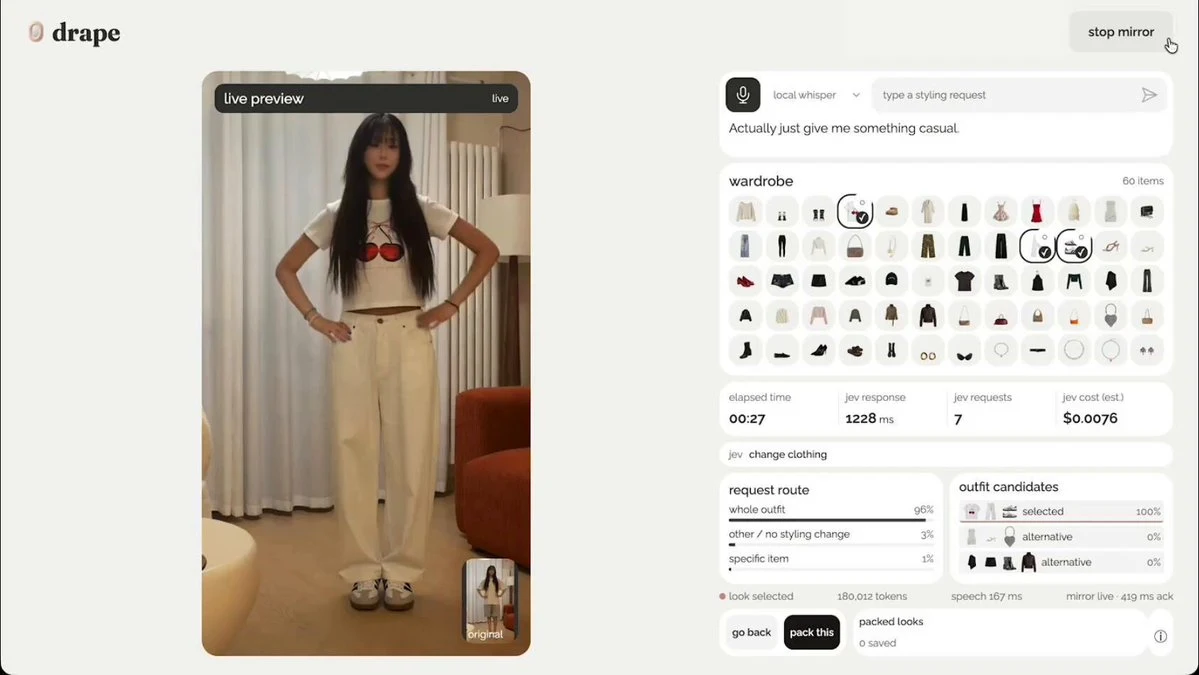
Interactive virtual try-on demo for Drape: reads speech transcript and current outfit, selects from closet, and swaps clothing in realtime at $0.0011 and ~620 ms per decision.
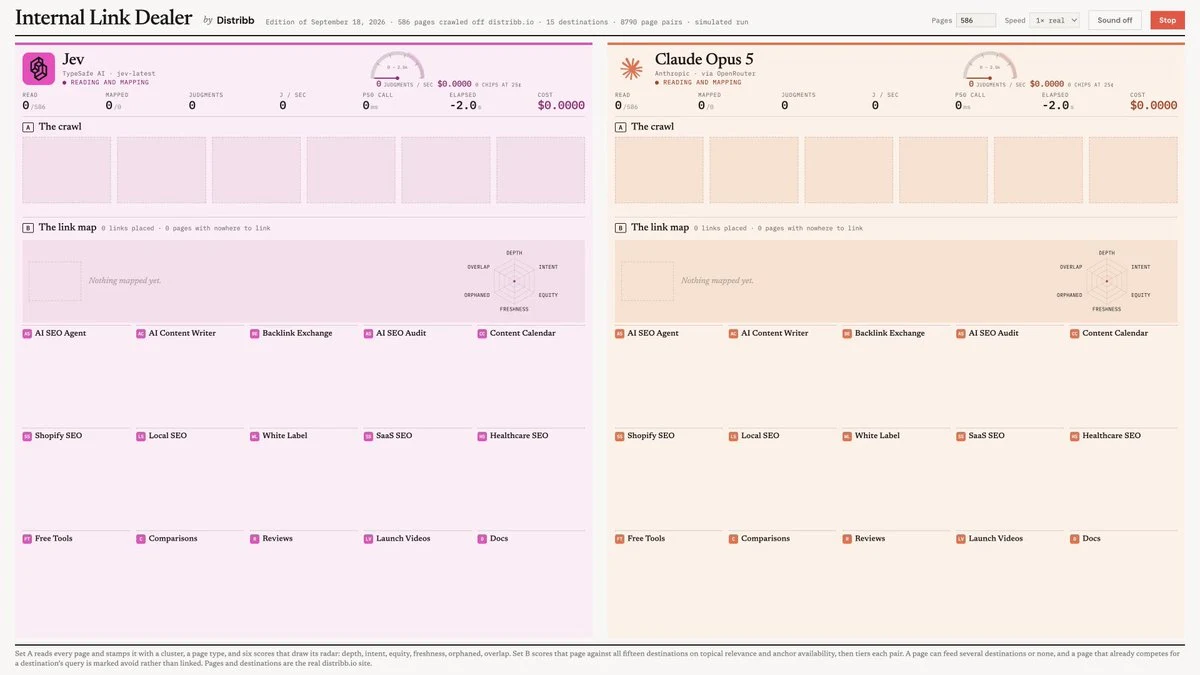
Crawled and rebuilt internal linking across 586 pages in 45.1 seconds for $0.21, placing 584 links and refusing 139 unfit pages. Demonstrates 190x cost reduction compared to Claude Opus 5 by treating internal linking as pure classification.
Live integration test wiring Jev via Vercel AI Gateway, measuring round-trip latency on structured schema payloads.
Detailed QA architecture breakdown contrasting traditional text-generating agents with deterministic, typed classification for test triage.
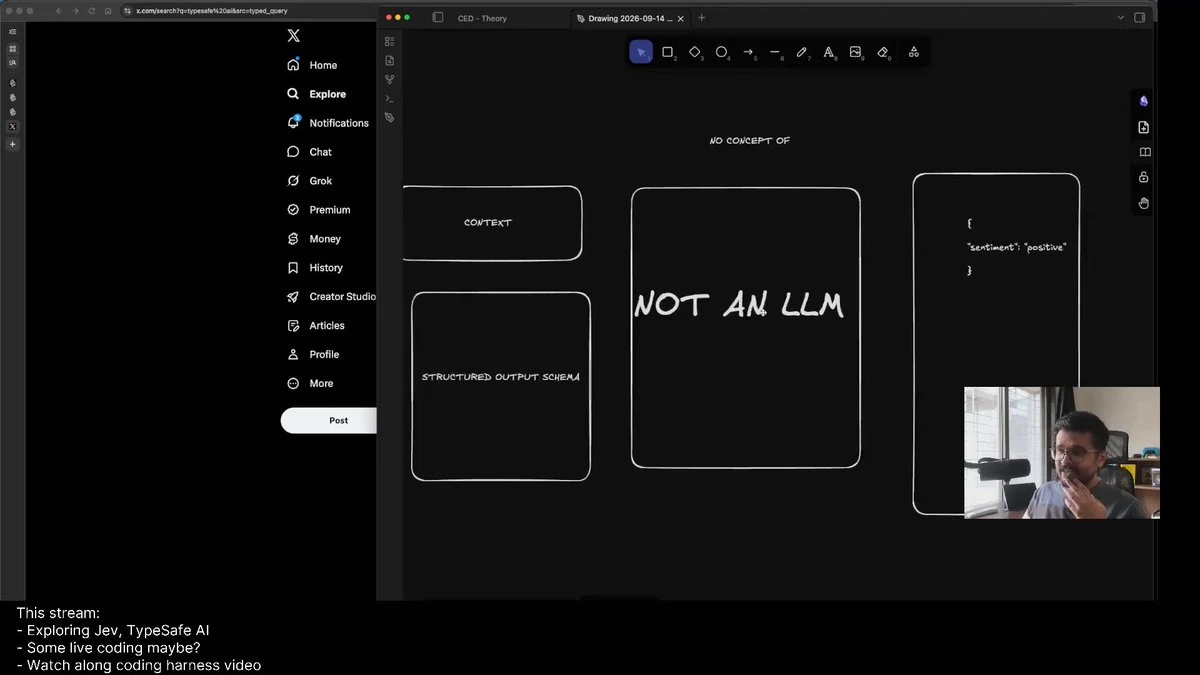
Live coding session testing prompt-free evaluation, payload batching, and DOM element decision trees.
Technical breakdown analyzing why stopping text generation is the necessary evolution for reliable software automation.
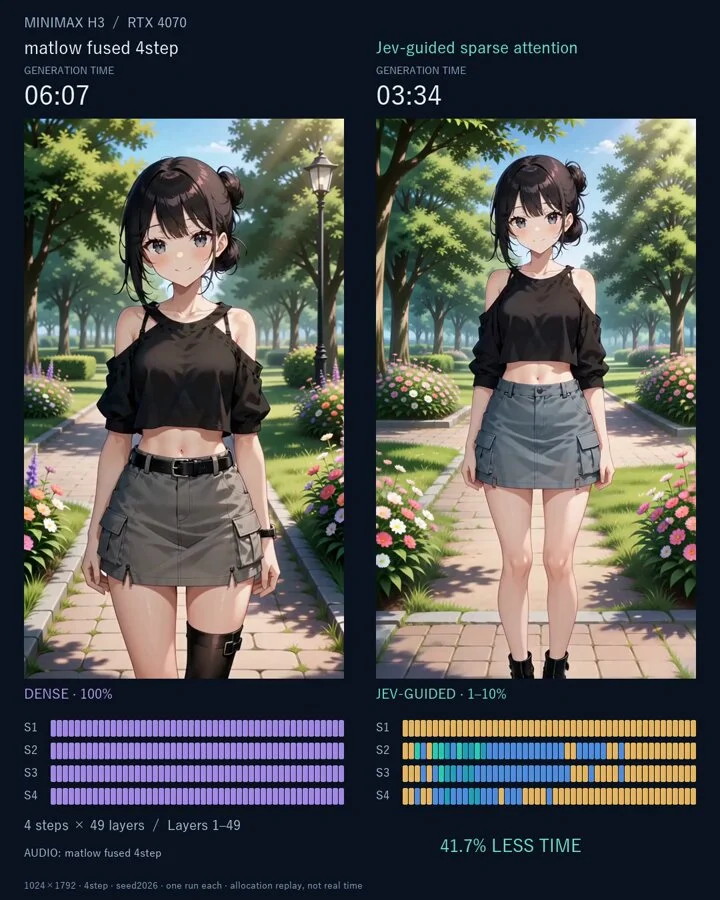
Kamimoto integrated Jev into ComfyUI for adaptive sparse attention across 50 DiT layers. This cut RTX 4070 generation time by 41.7% (6 m 07 s to 3 m 34 s) for $0.0392 across 20–30 videos.
Empirical reality check: stripped of candidate pre-filtering, Jev stacked blocks blindly in column 5 and topped out in 3 seconds. Demonstrates why System 1 cannot solve unconstrained spatial planning.
Evaluates natural language directives into shader uniforms and environmental wind vectors in sub-40 ms at 60 FPS without autoregressive token latency.
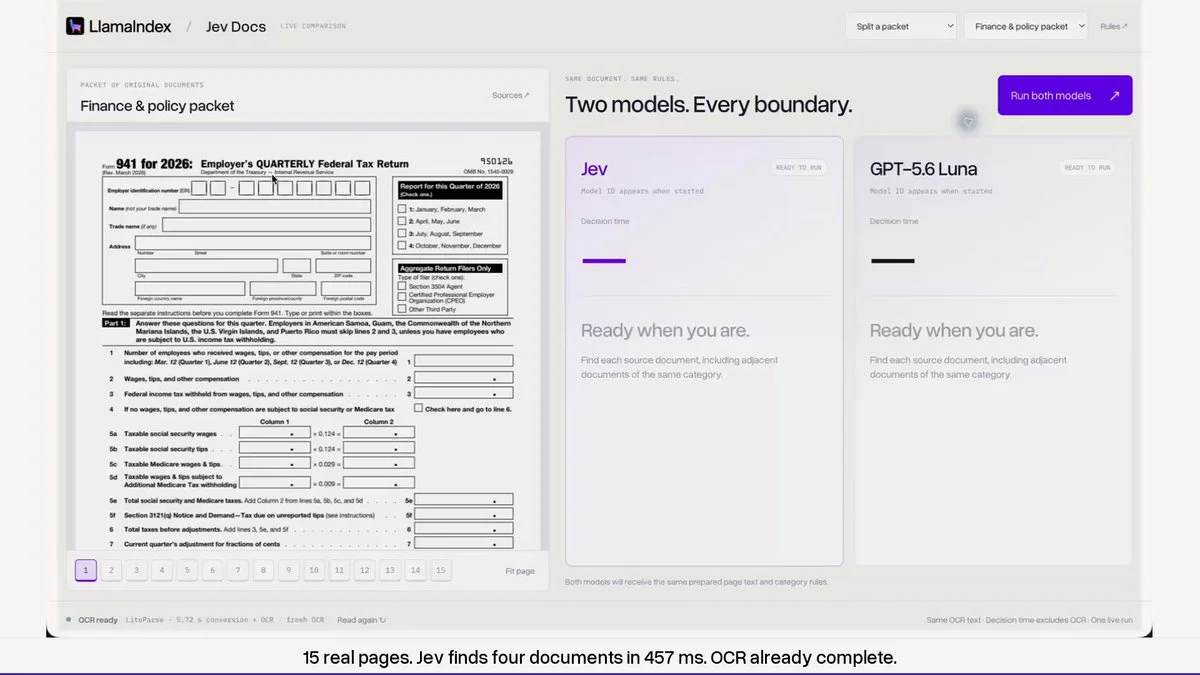
Demonstrates DocJev classifying and splitting complex document packets. It runs up to 6x faster than frontier models by coupling Jev decision routing with local LiteParse extraction.
The 187-tool ecosystem directory and launch repositories
⚡ Live Ecosystem Directory: Awesome Jev Visit awesomejev.org →
Since launch, the ecosystem has scaled beyond the initial prototypes into an authoritative production catalog hosted at awesomejev.org. The directory actively monitors 33 community mirrors and tracks tools across 9 canonical engineering domains.
- 187 Curated Tools: Evaluated against a Three-Prong Standard (Mechanism, verified Latency/Throughput, and Primary Evidence) with zero generated tokens.
- 1,993 Consensus Candidates: Continuously discovered and triaged via automated consensus scanning across 33 ecosystem mirrors.
-
Natural Language Intent Search: Built directly on Jev
(
POST /api/search) to classify developer problem statements and surface matching tools with a Curated vs All Tools scope toggle. - Interactive ROI Calculator: Quantifies monthly compute dollar savings and latency gains versus frontier LLMs like GPT-4o, Claude 3.5 Sonnet, and Gemini 1.5 Pro.
In the days following launch, the open-source community authored dozens of public repositories integrating Jev across distinct software engineering disciplines. Below are the foundational thirty-one repositories that established the core design patterns across seven key disciplines:
1. Browser, desktop, and mobile automation
jev-ultrafast(browser-use/jev-ultrafast): DOM element selection and web navigation without vision latency, evaluating interactive trees viachoicein under 100 ms.typesafe-computer-use(awlevin/typesafe-computer-use): macOS automation harness combining accessibility metadata to drive deterministic clicks and keystrokes.mobile-jev(droidrun/mobile-jev): Android device automation via Mobilerun, coordinating device actions while inspecting CLI and web execution logs.jev-voice-browser(moritzkremb/jev-voice-browser): Experimental voice interface that extracts user intent from browser speech recognition to navigate web pages via Playwright.unclutter(kitze/unclutter): Browser extension using Jev to identify and hide ad banners and modal popups.
2. AI development, code review, and context management
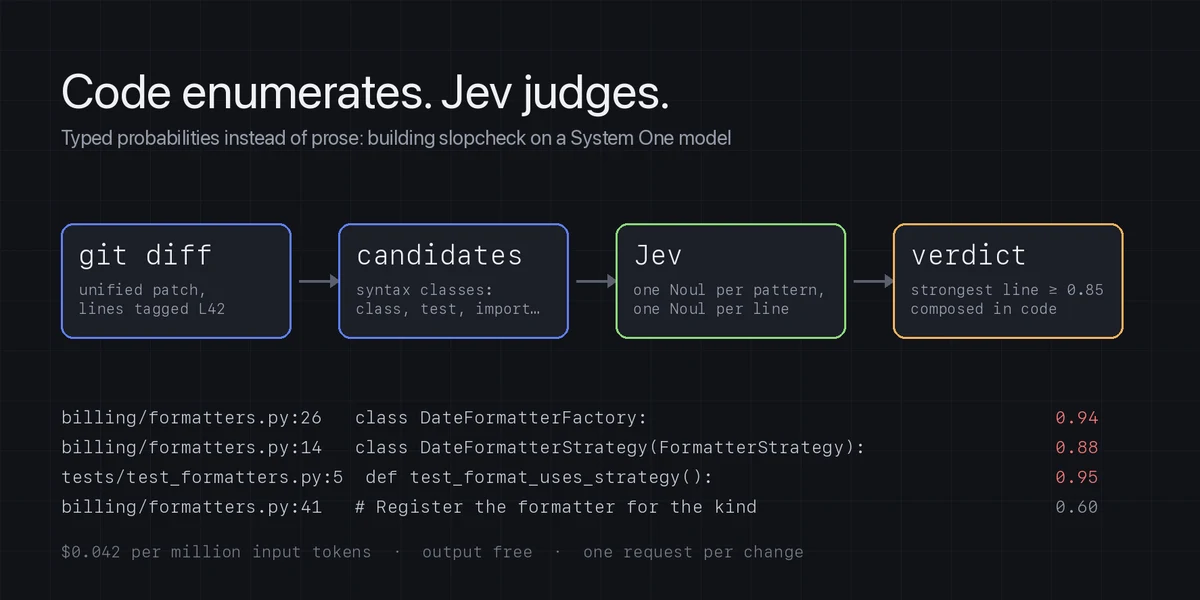
slopcheck(TjKlug/slopcheck): Git diff reviewer that uses deterministic AST extraction to find candidates, using Jev solely for semantic quality scoring.foreman(thruwire/foreman): Supervisory coordinator that oversees autonomous OpenAI Codex runs, deciding whether to continue, verify, or halt execution.jev-review(devagrawal09/jev-review): Step-by-step Git diff reviewer highlighting security risks and missing test assertions in pull requests.jev-router(gargpratyush/jev-router): Turn-by-turn dynamic model router dispatching between lightweight workers and deep reasoning models in Claude Code and Codex.jev-rules(EliaAlberti/jev-rules): Dynamically selects which project guidelines or reference docs to inject into Claude Code based on edited files.fast-jev-compaction(tamaratran/fast-jev-compaction): Context window compaction tool evaluated by Nous Research (see Teknium critique above).
3. MCP tools, skills, and shell integration
typesafe-mcp(itsmostafa/typesafe-mcp): Model Context Protocol server exposing Jev scoring, selection, and truth verification directly to Claude and Codex environments.skillbox(kitze/skillbox): Distribution platform for agent skills via MCP, using Jev to recommend tools matching current task requirements.jev-shell-history(mrnugget/jev-shell-history): Zsh shell plugin using Jev to select and auto-complete relevant commands from shell history.
4. Database filtering, search, and knowledge graphs
pg-jev(realZachi/pg-jev): PostgreSQL extension that filters, classifies, and ranks database rows using natural language conditions directly inside SQL queries.jev-search(superagents-lab/jev-search): Search pipeline delegating search term expansion, time-window selection, and relevance sorting to Jev.neo4jev(jexp/neo4jev): Graph exploration experiment directing relationship traversal across Neo4j nodes via Jev decision trees.docjev(jerryjliu/docjev): High-speed document classification and boundary splitting library by Jerry Liu (LlamaIndex). Uses Jev with LiteParse for local PDF, DOCX, and PPTX routing, running up to 6x faster than frontier models with optional LlamaParse OCR fallback.
5. Guardrails, SecOps, and content moderation
security-incident-containment(HavokSocial): Automated host isolation and firewall blocking conditioned on high-confidence typed classification.pi-warden(DevMortimer/pi-warden): Guardrail monitor for Pi agents, flagging project rule violations, repeated failures, and unverified task completion claims.notra(usenotra/notra): Generative Engine Optimization (GEO) tracker measuring brand mentions in AI responses using Jev for sentiment and ranking classification.Jev-Moderation-Bot(brainstormity/Jev-Moderation-Bot): Discord moderation bot detecting scam URLs and spam patterns.
6. Simulation, real-time gaming, and physical control
typesafe-mario(fhshaik/typesafe-mario): Emulator control experiment where Jev selects Mario game actions based on live memory state in under 16 ms.typesafe-smash(maubaron): Real-time 4-player Melee emulation where Jev controls four characters simultaneously directly from Dolphin RAM at 60 FPS across 22 million tokens.minecraft-agent(rmalde/minecraft-agent): Dual-system Minecraft speedrunEnder Dragon Speedrun (8 min 43 s)Astra plans async objectives while Jev selects real-time player actions in sub-20 ms with 0 output tokens. Defeated the dragon in 8 minutes 43 seconds for under $1.00 total ($0.01 Jev, $0.96 Astra).Ronak Malde’s Run Teardown → agent beating the Ender Dragon with 0 deaths.minimax-h3-jgas(sepiablue-ai/ComfyUI-MiniMax-H3-W4A4-VSA): J-GAS video generation accelerationMiniMax H3 Adaptive Sparsity (J-GAS)Kamimoto integrated Jev to dynamically judge Attention layer importance across 4 Turbo steps and 50 DiT layers, selecting sparsity retention rates (1%, 3%, 5%, 10%) in 0 output tokens. Generation time dropped from 6 m 07 s to 3 m 34 s (saving 153 s per video) for $0.0392 across 20 to 30 generated videos.Kamimoto’s J-GAS Teardown → dynamic attention pruning.interactive-doom(typesafeai): Real-time 3D combat agent navigating Doom without autoregressive decoding lag.jev-drone(RomanSlack/jev-drone): Drone simulation on the MuJoCo physics engine delegating real-time obstacle avoidance to Jev.jevpilot(standardagents/jevpilot): Autonomous driving experiment selecting routes and velocities in a Three.js simulator.threejs-grassworks-jev(Bk23544): Real-time AI Scene Director in Three.js by Bilal Khan (@Bk23544). Evaluates freeform natural language prompts via typed System 1 classification to dynamically modulate shader uniforms, sun angles, wind gust vectors, and blade sway in under 40 ms at 60 FPS.HA-Jev(AboveColin/HA-Jev): Home Assistant integration evaluating home sensor state for everyday household automations.jev-trader(jarrodwatts/jev-trader): Experimental trading bot testing buy and sell judgments on Monad via Kuru (defaults to dry-run mock executions).
7. Independent open-weight implementations
Several research efforts explore non-generative, typed judgment outside proprietary APIs:
SemIf(TheoLeeCJ/SemIf): Independent research reading choice probabilities directly from open model output heads.jevlike(vinnylarouge/jevlike): Training framework optimizing small language models to evaluate variable-length choice sets in parallel.NanoJev(TianyuCodings/NanoJev): Compact parallel judgment model based on Qwen3-0.6B weights with bundled emulator control demos.openjev-sglang(ekzhang/openjev-sglang): SGLang-compatible API implementation designed for high-throughput deployment on GPU clusters.Solomon 27b(Doccy / Archer Hume): Open-weight alternative based on Qwen3.8 27b with native multimodal evaluation, a 265k context window, multi-choice tagging, and evidence pointer spans.s1bench(bench.jakecuth.com): Multi-model benchmark matrixS1Bench: Decisions/s vs AccuracyJake Cuth evaluated 24 open-weight decision models against TypeSafe Jev across 1,999 decisions on DGX Spark. Jev set the frontier at 77.5% macro accuracy (2.4 decisions/s). Open models revealed steep tradeoffs: open-jev-deberta ran at 37 decisions/s but collapsed to 52.4% accuracy, while Qwen 27B reached 75.8% accuracy but required datacenter VRAM.Jake Cuth’s S1Bench Analysis → testing 24 candidate decision models against TypeSafe Jev.
Architectural patterns for builders
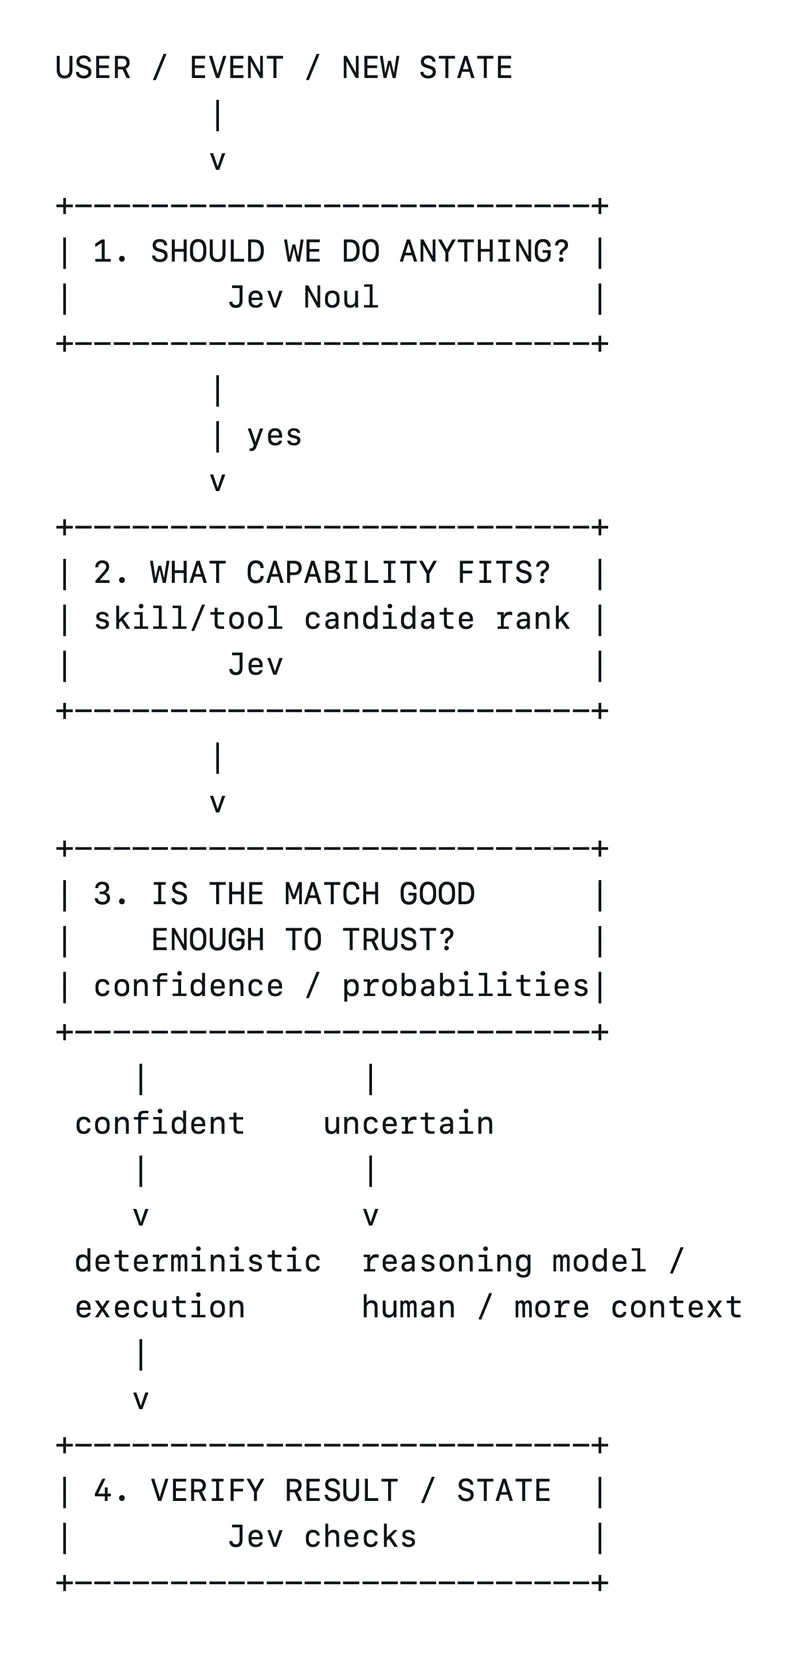
If you are incorporating a typed System One model into an existing software pipeline, structure your integration around four battle-tested architectural patterns:
┌──────────────────────────────────────────────────────────────┐
│                    Incoming Request / State                  │
└──────────────────────────────┬───────────────────────────────┘
                                │
                                ▼
┌──────────────────────────────────────────────────────────────┐
│ 1. Deterministic Extraction & Filtering (Code)               │
│    - Parse AST / DOM / log files                             │
│    - Strip irrelevant boilerplate                            │
│    - Enforce hard boundary rules                             │
└──────────────────────────────┬───────────────────────────────┘
                                │
                                ▼
┌──────────────────────────────────────────────────────────────┐
│ 2. Speculative Parallel Fan-Out (Jev)                        │
│    - Submit state + all primary and conditional questions    │
│    - Parallel execution in one GPU pass                      │
└──────────────────────────────┬───────────────────────────────┘
                                │
         ┌─────────────────────┴─────────────────────┐
         ▼                                           ▼
  Confidence ≥ 0.80                           Confidence < 0.80
┌──────────────────────────────┐            ┌──────────────────────────────┐
│ 3a. Automated Code Execution │            │ 3b. Fallback Cascade         │
│     - Deterministic branch   │            │     - Human review queue     │
│     - Fast-path execution    │            │     - Frontier LLM triage    │
└──────────────────────────────┘            └──────────────────────────────┘
Pattern 1: Speculative fan-out
Because questions are evaluated in parallel at virtually zero marginal cost, do not make sequential round-trips. Submit your primary classification questions alongside downstream conditional questions in the initial request:
{
  "state": "diff --git a/services/auth.py b/services/auth.py...",
  "questions": [
    {"id": "is_security_sensitive", "type": "noul", "query": "Does this patch modify authentication, token parsing, or credential handling?"},
    {"id": "risk_tier", "type": "score", "rubric": "1: trivial docs, 2: minor fix, 3: core logic, 4: security boundary"},
    {"id": "audit_action", "type": "choice", "options": ["auto_approve", "require_peer_review", "require_secops_review"]}
  ]
}
If is_security_sensitive comes back false, code simply
discards the audit_action result. You save an entire
network round-trip.
Pattern 2: The calibrated cascade
Use typed models as a high-throughput filter in front of expensive resources: 1. Deterministic code: Filters out obvious cases (known static assets, passing unit tests, exact schema matches). 2. System One model: Evaluates the ambiguous middle ground. If confidence ≥ 0.80, proceed immediately along the automated path. 3. Frontier model / Human review: Only the difficult remainder (confidence < 0.80 or high-stakes sensitive actions) is escalated to an autoregressive model like Claude 5 Sonnet or a human engineer.
Pattern 3: Code-owned composite scoring
Never ask a model to provide a single “holistic opinion” on a complex artifact. Ask granular, independent questions, and combine their probabilities using deterministic formulas in your own code:
Final Risk = w1 · P(unauthenticated) + w2 · P(exposes data) + w3 · P(breaks contract)
This pattern anchors weighting, thresholding, and business logic inside native code, allowing deterministic adjustments and audits without model retraining.
Pattern 4: Containment-gated SecOps automation
In security operations and infrastructure remediation, the boundary between automated intervention and human escalation is defined by confidence calibration. Rather than letting an unconstrained agent run arbitrary remediation commands, production incident pipelines use typed models to classify alerts against pre-approved playbooks:
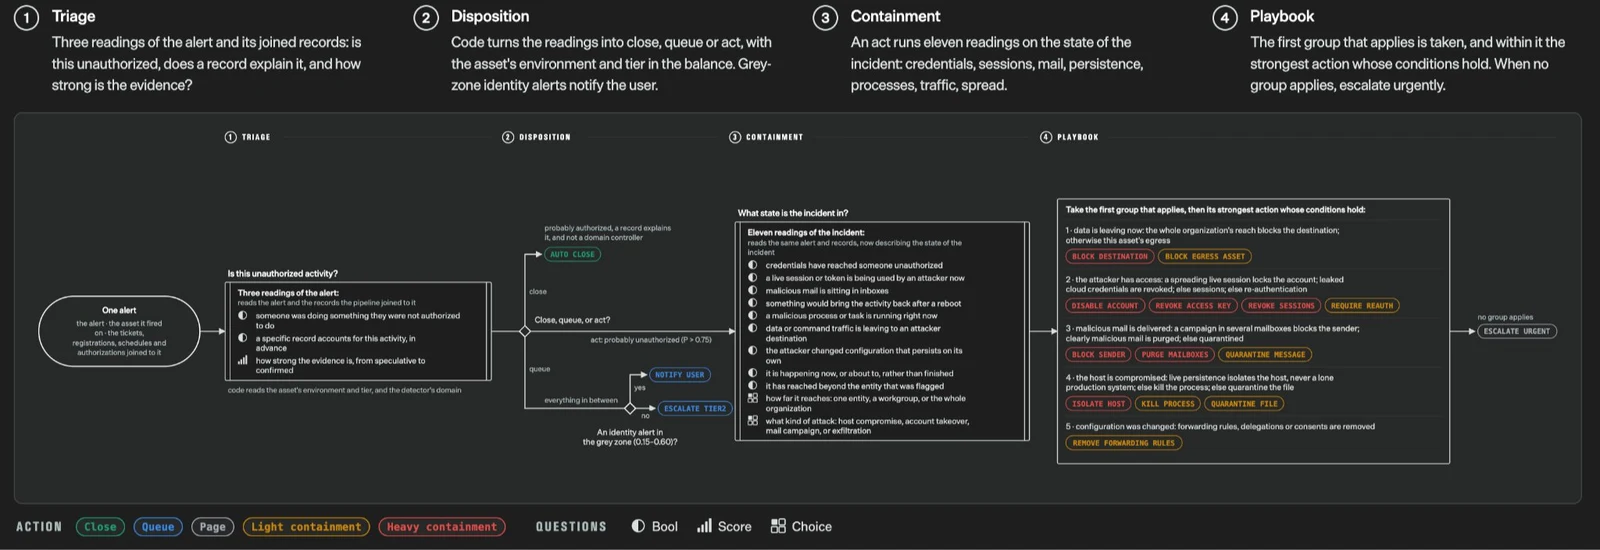
Under this model, read-only telemetry enrichment runs immediately. Low-risk containment actions (such as temporary rate-limiting) execute automatically when confidence exceeds 0.85. Disruptive interventions (such as revoking API keys or isolating database nodes) halt at the confidence gate and require explicit human confirmation.
Pattern 5: Dual-system economics and community production spends
In production, developers rarely run Jev in total isolation. Instead, they pair Jev with autoregressive foundation models. Jev acts as an inexpensive high-frequency reflex loop or filtering gate, while generative models handle macro planning or long-form drafting. Community benchmarks on X demonstrate how this division of labor shifts operational costs:
- 1,018 Paper Categorization (Hassan El Mghari, @nutlope): Summarized 1,018 papers using DeepSeek V4 Flash ($3.99 total, $0.004 per paper). Jev classified all papers across 24 candidate topics for $0.08 total ($0.000078 per paper) at 256 ms median latency.
- Autonomous Minecraft Speedrun (Ronak Malde, @rronak_): GPT-6 Astra planned macro objectives ($0.96 across 131 goal checkpoints). Jev executed real-time actions in sub-20 ms ($0.01 across 1,200+ ticks), defeating the Ender Dragon in 8 m 43 s for under $1.00 total vs estimated $50+ on pure frontier calls.
- 586-Page Technical SEO Audit (Borja Fatás, @borjafat): Crawled and rebuilt internal link graphs across 586 site pages in 45.1 s for $0.21 total. In the same 45.1 s, Claude Opus 5 processed only 21 pages and spent $1.43 (~190x more per page), projecting $43.00 for the full run.
- 60 FPS Super Smash Bros. Melee (Mau Baron, @maubaron): Controlled 4 characters simultaneously from Dolphin RAM at 60 FPS across 22 million input tokens. The entire 2-hour tournament run cost $0.92 on Jev vs an estimated $430+ on GPT-4o.
- DiT Video Generation Acceleration (Kamimoto, @sep_is_heim): Integrated J-GAS into ComfyUI for MiniMax H3 video generation across 50 DiT layers. Evaluated attention layer importance dynamically for $0.0392 across 20 to 30 videos (~$0.0015/video), cutting RTX 4070 generation from 6 m 07 s to 3 m 34 s (41.7% speedup).
- Social Media Stream Filtering (Braxxxx, @Braxxxx): Triaged 100 social media posts using Jev + ego lite against Claude Opus 4.8 and Claude Sonnet 5. Opus cost 63x more and took 4.7x longer. Sonnet cost 28x more and took 7.1x longer.
- Ambiguity Gating in Multimodal Generation (Pavel Sich, @sichy): DreamChat evaluated prompt ambiguity in 38 ms ($0.00002). It intercepted prompts when confidence fell below 34%, preventing wasted $0.05 vision and editing pipelines.
- Developer Agent Supervisory Triage (Darren, @TriadDarren): Four-stage supervisory triage for Codex and Claude Code developer agents. Jev gating at $0.00004 per step shields expensive reasoning steps ($0.03 to $0.08 per step), cutting overall agent spend by 90%+.
Conclusion: a missing primitive, not a silver bullet
The value of TypeSafe’s System One model is not that it replaces frontier LLMs, and certainly not that it replaces deterministic compilers or test runners.
Its value is that it provides a fast, inexpensive, typed bridge between unstructured text and deterministic code. It replaces brittle regex lists with semantic classification. It routes natural language queries when keyword search fails. And it provides calibrated probability distributions that code can safely branch on.
Treat it as an operational component: measure its performance against your own codebase, establish human baselines before believing metrics, keep your deterministic oracles strictly in code, and always verify what the limits actually bound.
Primary Sources: TypeSafe System One Launch Post · TypeSafe API Documentation · Valyu Practical Guide to Jev.
Academic References: Li et al., ICLR 2026 (Model Capacity in Evaluation) · Fine-Tuned Small Models vs Zero-Shot Classifiers.
Industry Teardowns: Twelve-Factor Agents Architecture · Alex Hitt Jev Ultrafast Video Teardown · Nous Research Hermes Agent PR #116246 · Paweł Huryn Jev Decisions Benchmark · The Product Compass.